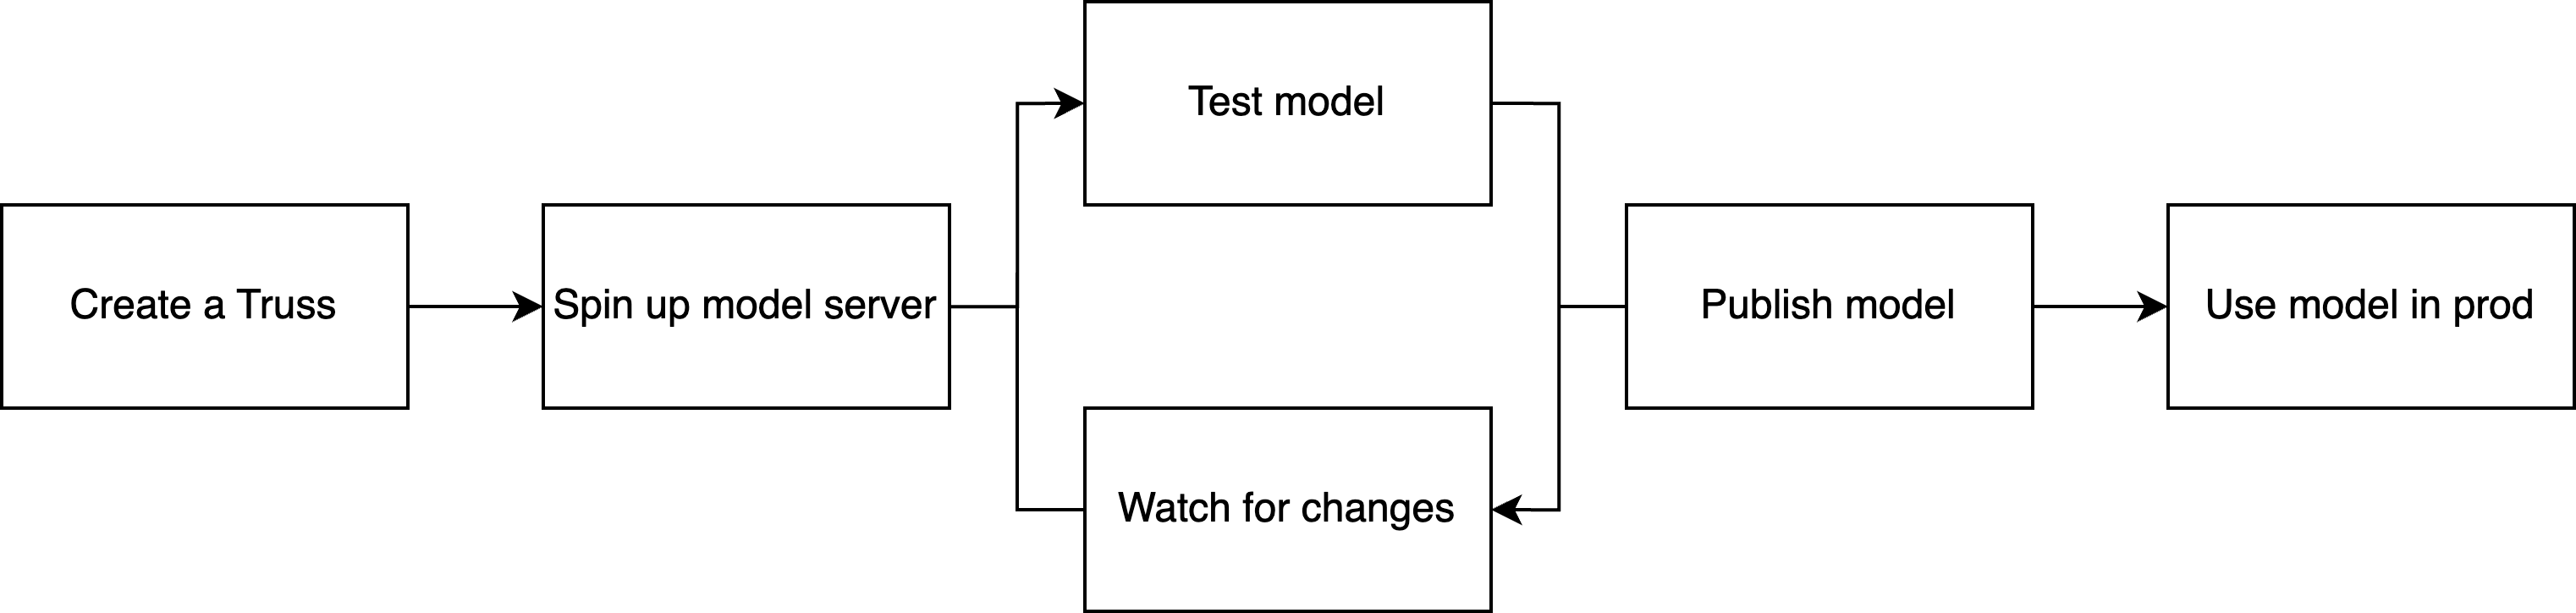
config.yaml file uses YAML syntax to define the model container, dependencies, and runtime configuration. Use the Baseten CLI to deploy and manage the package on Baseten with autoscaling and observability. To call a hosted model without deploying it, use Model APIs.
Choose how to serve your model
Start with the code or configuration you already have:- Model recipe or engine configuration: Follow Deploy your first model for an Engine-Builder-LLM endpoint, or choose a model recipe. Configure hardware, weights, and runtime behavior in
config.yaml. - Custom Python: Write a Model class when you need preprocessing, postprocessing, or prediction logic. Follow The development loop to deploy a Python Truss and test an edit.
- Existing inference server: Configure a model server to run Qwen with a vLLM container. Use Custom Docker servers to bring another container or serving framework.
- Multi-step pipeline: Use Chains when models or processing steps need separate hardware and scaling.
Deploy the package
Use the Baseten CLI to deploy your Truss project. Deploy a model shows the same model deployed from Explore, from a Truss project with the Baseten CLI, or through the Management API.