

Async requests work with any dedicated deployment. You don’t need code changes.
Requests can queue for up to 72 hours. Each inference attempt can run for up to
1 hour, and the inference retry policy can start additional
attempts. Async inference isn’t compatible with streaming output, and isn’t
available on Model APIs.
- Long-running tasks that would otherwise hit request timeouts.
- Batch processing where you don’t need immediate responses.
- Priority queuing to serve VIP customers faster.
Quick start
You need an active dedicated deployment, its expected input, and a Baseten API key inBASETEN_API_KEY. Set BASETEN_MODEL_ID to the model ID and BASETEN_WEBHOOK_URL to an HTTPS receiver you control. The receiver must accept POST requests and save their bodies before returning a successful response.
Prepare a receiver
To receive and save async results: Deploy the following receiver at your HTTPS webhook URL. Install its dependencies withpip install fastapi uvicorn and run uvicorn receiver:app --host 0.0.0.0 --port 8000 behind your HTTPS ingress. Use durable storage in production; this example saves each received body to a local file and prints the request ID:
receiver.py
BASETEN_WEBHOOK_URL must point to the receiver’s public HTTPS route, including /webhook.
Submit a request
To queue inference and correlate its result: Installrequests with pip install requests, then run the following script. Replace model_input with your model’s expected payload. An identity Truss returns this input unchanged:
Read the result
To confirm that the output arrived:-
Wait for the receiver to print
Saved result: YOUR_REQUEST_ID, matching the ID from submission. -
Open
results/YOUR_REQUEST_ID.jsonon the receiver. A successful identity-model result contains your original input indata:Received payload -
Check
errorsbefore acceptingdata. If no callback arrives, check request and webhook status, then inspect receiver logs.
errors array and the model’s output in data. Failed requests can deliver a payload with errors instead. For more information, see Webhook payloads and Inference errors.
webhook_endpoint is optional. If you omit it, /async_predict still returns a
request_id and the request runs normally, but Baseten has nowhere to deliver
the result. Because Baseten does not store model outputs, you must save them
yourself from inside the model (for example, from postprocess()). See
Webhook delivery. The status endpoint reports lifecycle
state only; it never returns model output.How async works
Async inference decouples request submission from processing, letting you queue work without waiting for results.Request lifecycle
When you submit an async request:- You call
/async_predictand immediately receive arequest_id. - Your request enters a queue managed by the Async Request Service.
- A background worker picks up your request and calls your model’s predict endpoint.
- Your model runs inference and returns a response.
- Baseten sends the response to your webhook URL using POST.
max_time_in_queue_seconds parameter controls how long a request waits
before expiring. It defaults to 10 minutes but can extend to 72 hours.
Autoscaling behavior
The async queue is decoupled from model scaling. Requests queue successfully even when your model has zero replicas. When your model is scaled to zero:- Your request enters the queue while the model has no running replicas.
- The queue processor attempts to call your model, triggering the autoscaler.
- Your request waits while the model cold-starts.
- Once the model is ready, inference runs and completes.
- Baseten delivers the result to your webhook.
max_time_in_queue_seconds, the
request expires with status EXPIRED. Set this parameter to account for your
model’s startup time. For models with long cold starts, consider keeping minimum
replicas running using
autoscaling settings.
Async priority
Async requests are subject to two levels of priority: how they compete with sync requests for model capacity, and how they’re ordered relative to other async requests in the queue.Sync vs async concurrency
Sync and async requests share the model’spredict slots, set by
predict_concurrency in your model configuration:
config.yaml
predict_concurrency limits how many
requests run predict at once in a replica. Preprocessing and postprocessing
run outside that limit. When both sync and async requests are in flight, sync
requests take priority. The queue processor monitors your model’s capacity and
backs off when it receives 429 responses, ensuring sync traffic isn’t starved.
For example, if your model has predict_concurrency=10 and 8 sync requests are
running, only 2 slots remain for async requests. The remaining async requests
stay queued until capacity frees up.
Async queue priority
Within the async queue itself, you can control processing order using thepriority parameter. This is useful for serving specific requests faster or
ensuring critical batch jobs run before lower-priority work. Set the priority field when you submit the request:
async_predict.py
priority parameter accepts values 0, 1, or 2. Lower values indicate higher
priority: a request with priority: 0 is processed before requests with
priority: 1 or priority: 2. If you don’t specify a priority, requests
default to priority 0.
Because unspecified requests default to priority 0, use the priority parameter
mainly to demote less urgent work: set background or batch jobs to priority: 1
or priority: 2 so they yield to default-priority traffic. Marking every request
with the same priority has no effect on ordering.
Watch the queue
Two things decide how quickly an async request clears: itspriority against the
other requests in the queue, and how it competes with sync traffic for replica
capacity. The simulation below shows both. Requests pile up in the async queue, a
load balancer pulls the front of the queue and sends each request to a free replica,
and the replica runs it and frees up for the next.
Requests arrive at the back of the queue and cut ahead of every lower-priority
request, so a priority 0 jumps to the front. The load balancer clears the queue as
fast as it can, always dispatching the front request, so higher-priority work reaches
a replica first. The figure shows each replica handling one request at a time. Switch
to Sync contention to add sync traffic: sync and async share replica capacity, and
sync takes precedence. Sync requests go straight to the replicas, so when sync surges
the load balancer cannot place async work and backs off when it hits a 429. As the
surge recedes, the load balancer drains the backlog across the freed replicas.
Webhooks
Baseten delivers async results to your webhook endpoint when inference completes.Request format
When inference completes, Baseten sends a POST request to your webhook with these headers and body:HTTP request
X-BASETEN-REQUEST-ID header contains the request ID for correlating webhooks with your original requests.
The X-BASETEN-SIGNATURE header is only included if a webhook secret is configured.
Webhook endpoints must use HTTPS (except
localhost for development). Baseten
supports HTTP/2 and HTTP/1.1 connections.Webhook payload
request_id matching your original /async_predict
response, along with model_id and deployment_id identifying which deployment
ran the request. The data field contains your model output on success. Check errors before using it; a failed request may not contain model output. The errors array is empty on success, or contains error
objects on failure. For what each status code means and how to respond, see Inference errors.
Webhook delivery
Baseten delivers webhooks on a best-effort basis with automatic retries:
To prevent data loss:
-
Save outputs in your model. For a Python Truss, add a
postprocessmethod that accepts a typedRequestand reads the async request ID from its headers. Addboto3to your requirements and configure AWS credentials and write access to your S3 bucket before using this method:The async worker suppliesmodel/model.pyX-BASETEN-REQUEST-ID. This method requires that header. If your model also serves other request paths, handle calls without it or supply an application-level correlation ID. Save per-request values in local variables, since requests can run concurrently. Storage failures raise an error rather than returning a result that wasn’t saved. - Use a reliable endpoint. Deploy your webhook to a highly available service like a cloud function or message queue.
Secure webhooks
Create a webhook secret in your workspace’s Secrets settings. Use the webhook secret for signature verification, rather than a model secret or your Baseten API key. When configured, Baseten includes anX-BASETEN-SIGNATURE header:
HTTP header
False:
verify_signature.py
v1 signature in the header using compare_digest. During rotation, the header can contain signatures for both the old and new secrets; accepting a matching signature allows the receiver to switch to the new secret.
Rotate secrets periodically. During rotation, both old and new secrets remain
valid for 24 hours.
Manage requests
You can check the status of async requests or cancel them while they’re queued.Check request status
To check execution and delivery status: SetBASETEN_REQUEST_ID to the ID returned by submission, then run the following script. This captured response is from a request that saved its output inside the model without a webhook:
status describes execution and webhook_status describes delivery. Neither field contains the model’s output.
Status is available for 1 hour after completion. See the
status API reference
for details.
The status and cancel endpoints take a model ID and a request_id only; there’s no environment segment in the path. A request_id is globally unique, so you don’t need to know which environment or deployment originally accepted the request to look it up.
Cancel a request
OnlyQUEUED requests can be canceled. Once a request enters IN_PROGRESS, the cancel endpoint can’t stop it: the request runs to completion (or fails). If you need to bound how long a request can wait before running, set max_time_in_queue_seconds on the request so stale requests transition to EXPIRED instead of executing.
To cancel queued work:
Set BASETEN_REQUEST_ID to the request ID, then run the following script. Check the canceled field to confirm whether cancellation took effect:
canceled: true when cancellation succeeds. If it has already started or completed, the response returns canceled: false, as in this example.
For more information, see the cancel async request API reference.
Error codes
When inference fails, the webhook payload returns anerrors array:
Webhook payload
Inference retries
When inference fails with a retryable error, Baseten automatically retries the request using exponential backoff. Configure this behavior withinference_retry_config:
async_predict.py
Retries use exponential backoff with a multiplier of 2. With the default three
attempts, the two retries wait 2 seconds and 4 seconds. If you increase
max_attempts, later delays reach the 5-second max_delay_ms cap.
Only requests that fail with retryable error codes (500, 502, 503, 504) are
retried. Non-retryable errors like invalid input (422) or model not found (404)
fail immediately.
Inference retries are distinct from webhook delivery retries.
Inference retries happen when calling your model fails. Webhook retries happen
when delivering results to your endpoint fails.
Rate limits
There are rate limits for the async predict endpoint and the status polling endpoint. If you exceed these limits, you’ll receive a 429 status code.
Polling
/async_request/{request_id} returns request lifecycle status
(QUEUED, IN_PROGRESS, SUCCEEDED, and so on) but never returns the model
output. Use a webhook, or persist the output from within your model, to receive
results. Prefer webhooks over polling to avoid the status endpoint rate limits
above. Contact support@baseten.co to request
increases.
Observability
Async metrics are available on the Metrics tab of your model dashboard:- Inference latency/volume: includes async requests.
- Time in async queue: time spent in
QUEUEDstate. - Async queue size: number of queued requests.
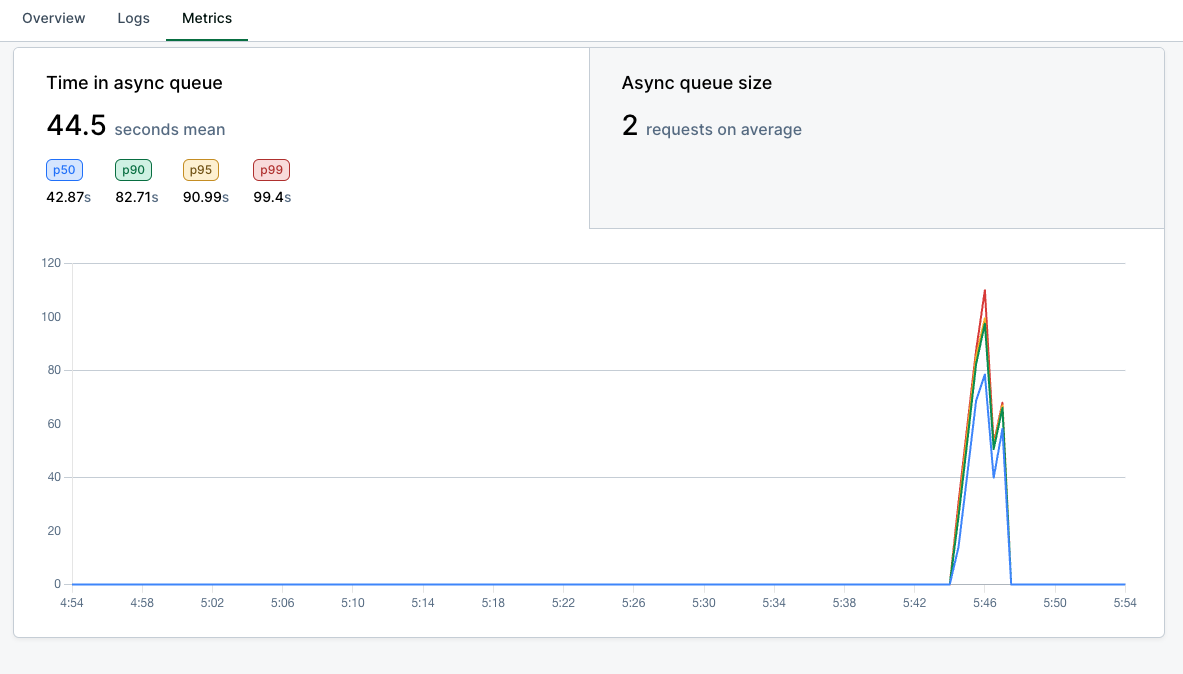
Async queue metrics in the dashboard
Related
Webhook secrets
Configure webhook secrets in your Baseten settings to secure webhook delivery.